


Course
6 Steps to Documentation You Don't Write
Lesson 3 of 6


The page was written on Tuesday. It went live sixteen days later.
Nobody was slow. The draft took an afternoon. The other fifteen days went into getting three people to look at it: an engineer who kept meaning to, a colleague who reads well and had a release on, and you, waiting for both before you’d publish.
That’s the shape of the problem now. Writing stopped being the expensive part. Waiting took over.
60+ product and documentation teams at B2B SaaS companies, interviewed through 2025 and 2026: teams that lost their writers, teams that never had one, and teams where the writers never left.
In the teams without this delay, nobody was asking for review as a favor. It arrived where the work already was.
When documentation was written by a dedicated team, review was a handoff between two functions and the delay was visible: the writers were the queue, and everyone knew it.
Now drafting takes an hour and the queue is invisible. It’s spread across three people’s inboxes, none of whom is doing anything wrong. The work sits in a state that no tracker reports on, because nothing is blocked in a way anyone can see.
How long this gets is worth being blunt about. A documentation lead at an engineering software vendor (1000+ employees, Eastern Europe) described the worst case she’d been through: “The glossary took me a month to get approved, because the people signing off couldn’t work out what we were trying to say.”
A month, for definitions of words the company uses every day. Nobody objected to the glossary. There was simply no forcing function to make anyone decide.
Nobody in your process is refusing to review documentation. They’re just never getting to it, and nothing in your process notices.
The standard explanation is cultural: engineers don’t respect documentation, subject-matter experts don’t take it seriously. We heard versions of this in interviews, sometimes bitterly — writers describing experts who dodge review and treat their work as an afterthought.
The feeling is real. The diagnosis is wrong, and it leads to solutions that don’t work — chasing, escalating, reminding.
Look at it from the engineer’s side. Their week is organized around things they’re accountable for: their tickets, their pull requests, their incidents. All of it flows through one or two tools, has a queue, and gets noticed when it stalls. Your review request has none of those properties. It arrives as a message, lives in no queue, appears on no board, and its absence blocks nothing anyone measures.
It loses for a structural reason, not a cultural one: it’s the only item in their week with no claim on their attention.
There’s a second thing happening, subtler and worth naming. Sometimes what looks like avoidance is uncertainty about what’s being asked. “Can you review this?” is an unbounded request — check the facts? the tone? whether we should have written it at all? An expert who isn’t sure what they’re approving, and suspects they’re being asked to share responsibility for something they don’t control, will reasonably let it sit.
Review loses to everything else because it’s the only task in your process that lives outside everyone’s job description. Fix the routing, not the attitude.
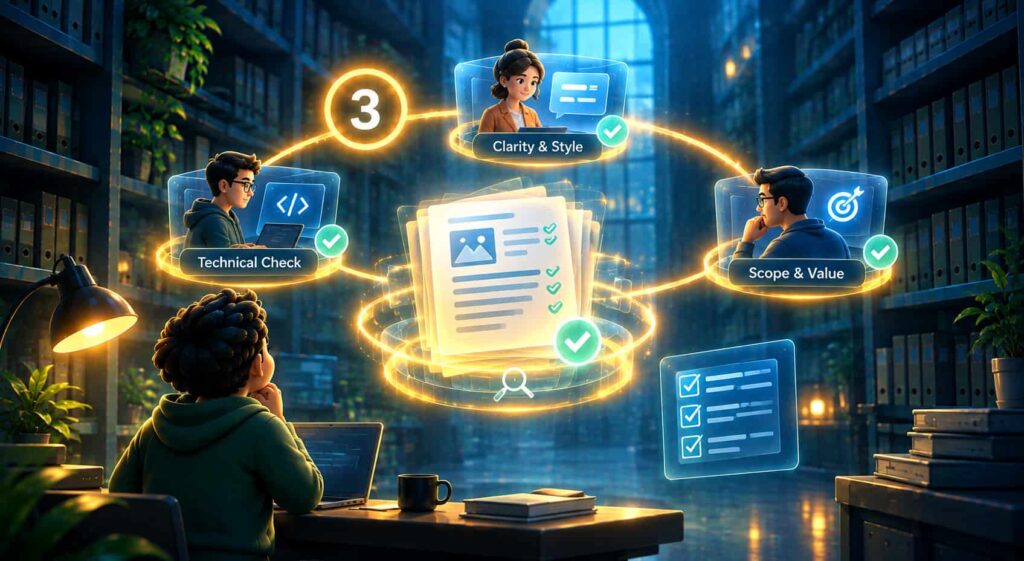
Start by splitting the request, because “review this page” is three different jobs that happen to arrive together:
Is it true? Do the steps work, does the code run, are the permissions and limits described correctly? Only someone who built it or tests it can answer. This is the check that protects customers from being actively misled.
Is it clear? Does it read well, is the terminology consistent, is it in the right register for the audience? Anyone with a good ear can do this. It matters, and it is almost never urgent.
Should it exist in this form? Does it cover a job worth covering, does it match how we position the feature, is anything missing that a customer will need? That’s the accountability from the last lesson, and it stays with you.
Bundling all three into one message is what makes review feel heavy. The engineer opens your page and doesn’t know whether they’re being asked to check facts or approve prose, so they read the whole thing carefully, which takes forty minutes they don’t have, so they postpone it.
Split it and the technical check becomes what it should be: five minutes on the two paragraphs that contain claims about behavior.
Three questions, three different people, three different levels of urgency. Sending them as one request is why you’re waiting.
A developer tools vendor (1000+ employees, Eastern Europe) described the cleanest version of this we came across, and it’s built entirely on separation.
Technical accuracy goes to the engineer who built the feature, and only that. They’re asked one question: does the product do what this says, and do these code samples run? Nothing about wording. Nothing about whether the topic should exist.
Language goes to a native-speaker editor, in a separate pass, after the facts are settled. It doesn’t hold anything up, because a page with correct facts and slightly clumsy phrasing is publishable; a page with elegant phrasing and wrong permissions is not.
Meaning and positioning go to whoever owns that part of the product, who checks that a new feature is described the way the company wants it understood.
What makes this work sits underneath the three-way split. Documentation is treated as the whole squad’s output rather than one person’s request, so nobody is doing anyone a favor. The page is part of what the team ships, and checking it is part of shipping it.
They don’t send one message asking for a general opinion. They don’t ask the engineer about wording, which is the fastest way to lose an engineer. And they don’t let the language pass block anything, which is why nobody feels the process as friction.
The change that moved the needle in our interviews has nothing to do with process design. It’s location.
In teams with a strong engineering culture, documentation changes travel the same road as code. At the developer tools vendor above, API changes generate merge requests automatically, and a documentation lead there described the routine in one sentence: “Every morning the writers come in and work through whatever landed overnight.”
Nobody had to be persuaded to care, because nothing about the routine changed. The item showed up where their attention already goes.
One team we spoke to has AI agents open documentation pull requests automatically when the underlying code changes, and the humans review those PRs like any other. Forget the automation for a moment. The useful detail is that a machine-generated draft still lands in a human queue with a structure.
The general rule holds even without a code-based workflow: whatever tool your experts live in — the tracker, the code host, the chat channel with a real queue — that is where review requests should arrive. Not in a document-sharing notification they’ll see once and forget.
A review that requires someone to visit a new tool is a favor. A review that lands in the queue they already work through is work.
Here’s the part most teams miss entirely.
Your testers already read the documentation. They read it to write test cases, because the description of intended behavior is the specification they check against. And in doing that, they are the first people in the company to notice when the product and the documentation disagree.
This has a name in QA practice. Checking that a product behaves the way its documentation says is an established type of non-functional testing —documentation testing, with a defined place in QA practice. The stated benefits are exactly what you want: problems caught early, fewer support requests later, less training needed. Teams we interviewed described testers flagging inaccuracies in documentation as a matter of course, sometimes more reliably than anyone formally assigned to check it.
So the ask changes shape. You’re not requesting a favor from a busy department. You’re asking QA to record something they already encounter, in the same place they record everything else they find.
That’s a smaller request than “please review our docs,” and it goes to people whose entire function is comparing claims against reality.
There’s a second reason to have this conversation now. QA teams are using models to generate test cases from scenarios, and those models produce far better results when they’re grounded in current documentation rather than in whatever they can infer from the codebase and the ticket title. Accurate docs make their automation cheaper. That’s a real interest of their own, and interests survive reorganizations in a way that goodwill does not.
One warning, because this cuts both ways. If test cases are generated from documentation and the documentation is wrong, the tests encode the error and both sides agree with each other forever. The mismatch check only works while at least one side is checked against the product itself. Worth saying out loud when you have the conversation.
Three checks, and for each one: who, where, and whether it stops the page from going live.
| Check | Who | Where it happens | Blocks publication? |
| Is it true? | Engineer who built it; QA for behavior | Same queue as their normal work | Yes |
| Is it clear? | Anyone with a good ear; editor if you have one | Wherever is convenient, after facts are settled | No |
| Should it exist in this form? | You — the area owner | Before writing starts, not after | Yes, but earlier |
Three things this table decides that normally stay implicit.
Only one check blocks. If everything blocks, nothing is prioritized and the whole thing becomes the ceremony people route around. Facts block because publishing wrong instructions costs customers real time. Phrasing doesn’t.
The scope check happens before the writing. Asking “should this exist?” after a draft is finished wastes the draft and puts you in the position of rejecting someone’s work. Ask it first and it takes two minutes.
“Where” is a location, not a person. This is the column teams skip, and it’s the one that determines whether any of this survives contact with a busy week.
The routing table is useless if the process it describes is optional.
Your team already has a mechanism for this and uses it for everything else: the definition of done. A feature is done when it meets the criteria the team agreed on, not when the code merges. Documentation either appears in that list or it doesn’t, and if it doesn’t, it will keep being the thing that happens after the release, if there’s time.
Be careful about what you put there. The temptation is to require full documentation for every ticket, which is how definitions of done become fiction — everyone agrees to it and nobody enforces it after the second sprint.
A version that survives contact with reality looks more like this: a feature is done when the jobs it introduces are covered and the factual check has passed. Language polish isn’t in the definition. Neither is a page for every ticket. One condition, tied to the thing that actually harms customers when it’s wrong.
Until documentation is in your definition of done, it belongs to the period after the release, when there’s time. There is never time.
Not everything requires review, and pretending otherwise is how processes collapse under their own weight.
Internal notes, runbooks in progress, drafts shared for comment, anything where the cost of being wrong is a colleague asking a question — none of that needs a routing table. Applying formal checks to low-stakes writing teaches your team that the process is theater, and then the checks that matter get treated the same way.
The test is simple: if a mistake here would reach a customer, route it. If it wouldn’t, publish it and move on.
Fix the routing and review stops being a negotiation. It becomes a step that happens because it’s in the way of something people already care about finishing.
But a page that’s accurate, well-phrased, and approved by everyone can still be a page nobody needed. Review confirms your documentation is correct. It can’t tell you whether it’s working. That’s next.
Try it before deciding. Much of what reads as indifference is a request with no queue and no boundary. When the ask is “confirm these two claims about behavior” and it arrives in their normal review flow, people answer it, and nobody’s attitude had to change.
It becomes optional, and that’s acceptable. Read it aloud yourself, or ask a colleague with a good ear when there’s a lull. Clarity matters, but a slightly awkward accurate page serves customers better than a polished one that sits unpublished for two weeks.
Ask QA. They tested it, and their test cases encode the intended behavior. Failing that, whoever owns that part of the codebase now — the check is about current behavior, not history.
That’s a bigger decision than this article can make for you, and it depends on how much of your customer contact happens through docs. Start with blocking publication rather than blocking release: it’s enforceable immediately and doesn’t require org-wide agreement.
It runs faster, and the reason is arithmetic. One combined request takes forty minutes of an engineer’s attention, which is why it waits. Three targeted requests take five, ten, and two minutes, and they run in parallel.
Get monthly digest on technical writing, UX and web design, overviews of useful free resources and much more.
"*" indicates required fields
 How to Manage Multiple Product Manuals Without Duplicating Content
 Structuring documentation for multiple products: what to separate and what to share
 Release Notes & Changelog Automation: How to Stop Writing Manually
 Snippet Management in Technical Documentation: Stop Copy-Pasting, Start Reusing

