


Course
6 Steps to Documentation You Don't Write
Lesson 4 of 6


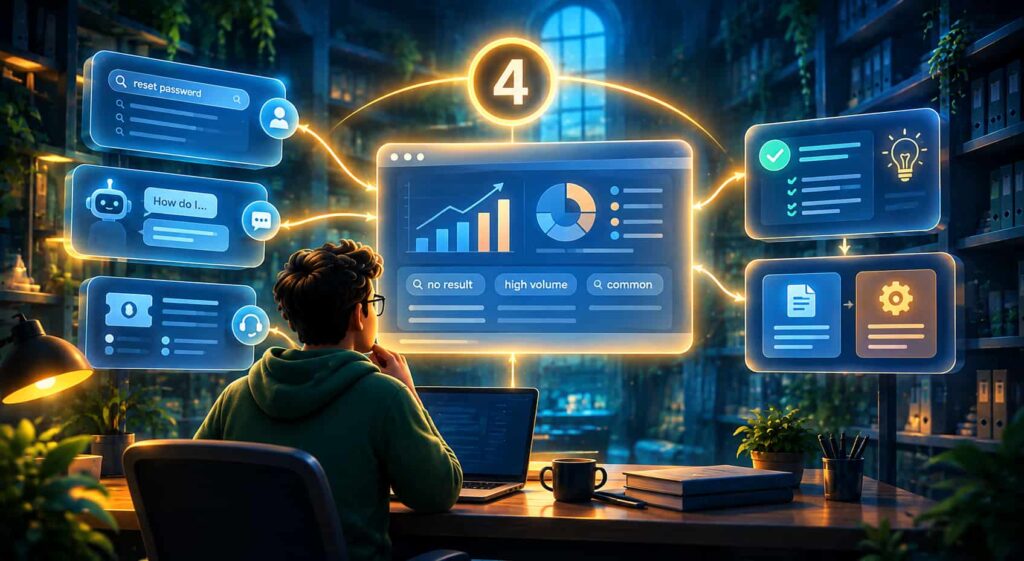
Every day, people tell your company where your product confuses them, what they expected it to do, and which words they use for it. They type it into your search box. They ask your assistant. A few of them open a ticket. Almost none of it is read by anyone whose job is to notice patterns.
60+ product and documentation teams at B2B SaaS companies, interviewed through 2025 and 2026: teams that lost their writers, teams that never had one, and teams where the writers never left.
The clearest thing separating the teams whose documentation worked from the teams whose documentation didn’t: whether customer questions went anywhere after they were answered.
When teams measure documentation at all, they measure page views. The number is available, it goes up and to the right when you publish more, and it feels like data.
Look at what it actually reports. Someone arrived. That’s the whole message. A page with two thousand visits a month might be the most useful thing you’ve published, or it might be a page where two thousand people looked for something, failed to find it, and opened a ticket. The number is identical either way.
Page views tell you a page was opened. They cannot tell you whether anyone left with an answer.
Plenty of teams don’t even have that much. A product manager at a European CRM vendor (B2B SaaS, 500+ employees) told us his team had no reporting on documentation readership at all: “it’s a topic where we are a bit blind.”
Blind is the normal starting condition, and the fix isn’t a better dashboard. Good signal already arrives every day and goes straight in the bin.
When the same question arrives for the third time, it means one of exactly two things:
The answer isn’t there, or isn’t findable. That’s a documentation gap. It goes in a documentation backlog and gets fixed by writing or reorganizing.
The answer is there and people still need to ask. That’s a product problem wearing a documentation costume. Something in the interface is telling people the wrong story, and no page will fully compensate for it.
The second is worth more and gets lost more often: once support answers, the ticket closes and nobody asks what it was really about.
Every repeated question is either an answer that isn’t there or a product that shouldn’t need one. Sorting them is the work, and nobody is currently doing it.
Sorting is also cheap. It’s a judgment call made by someone who knows the product, applied to a list that already exists.
Tickets are the obvious place to look, and the worst place to stop.
A ticket is what’s left after someone searched, failed, asked a colleague, and decided the problem was worth twenty minutes of writing. Everyone who gave up earlier is missing from that queue, and they’re the majority. Worse, tickets skew toward your loudest accounts, which is exactly how documentation and roadmaps end up shaped by whoever complains most.
Two sources sit upstream of that, and both are better.
Search queries inside your documentation. These are your customers’ own words, unedited by support, from people who never contacted anyone. The no-result queries are the interesting half: each one names a gap in the vocabulary your customers actually use. The other half matters too — a high-volume query where you know a good page exists means people are searching for something they should have found by now.
Conversations with the assistant on your docs, if you have one. This is the only source that records what happened after an answer was given. When someone reads a response and replies “that doesn’t work,” “I still can’t see it,” or “I tried that already,” you’re watching the product bucket separate itself from the documentation bucket in real time. No sorting judgment required — the customer did it for you.
A support ticket is a question that survived three earlier attempts to get an answer. Read the search box instead: it records the attempts.
Tickets give you anecdotes; search gives you counts. Deciding which of four gaps to close first, forty searches beats one very annoyed email — and it’s a far easier case to make to a team that has other work.
General-purpose analytics will get you there. Google Analytics records site search if someone configured it, your chatbot vendor exports conversations, and between them you can reconstruct most of the picture with a few exports and a spreadsheet. Documentation platforms tend to report it directly: in ClickHelp, for example, search queries come with a no-result filter and assistant conversations are logged with the follow-ups attached, so “where did we have nothing to say” is a filter rather than an afternoon of joining exports.
Either way, the fifteen-minute version is the same: sort last month’s queries by volume, read the top twenty, mark the ones where you know a good page already exists.
Weakest source doesn’t mean skip it. Tickets are the easiest thing to wire up, and they’re the only source where a named customer is attached to the question. One team started there.
A developer tools vendor (1000+ employees, Eastern Europe) built the simplest version of this we came across, and it took no new tooling.
Support agents got the ability to file documentation issues directly against a topic. Not a general request in a shared channel — an issue attached to the specific page, with a link back to the customer ticket that prompted it.
That link is the part that matters. It converted “the docs are unclear” into a traceable item: this customer, this question, this page, this day.
Two things followed. The backlog started reflecting reality instead of intuition, and the topics that got attention turned out not to be the ones the team had assumed. And when one topic collected several issues in a month, that pattern became visible to someone who could do more about it than rewrite a page.
The mechanism transfers to a company of forty with no tooling at all: a shared list, a link to the ticket, and a rule that support adds to it instead of only answering.
When you start collecting, the items sort into four kinds. The first three came up repeatedly in our interviews as the categories teams treat as urgent:
The first three get reported. Someone hits them and complains.
The fourth doesn’t. Nobody files a ticket about a page that quietly stopped matching the product; they just lose a little confidence and work around it. This is how a portal rots while every individual page looks fine.
Documentation testing from the last lesson catches some of this, inside whatever area is being tested. Staleness lives everywhere else: a screen that changed as a side effect of something unrelated, a permissions model that quietly gained a role, a limit that moved. Nobody checks those pages because nobody is looking at that area at all.
Lesson two left a gap on purpose: the ownership grid covers a page up to publication and stops.
The instinct is to assign someone, and it fails for a structural reason. “Keep documentation up to date” is a standing responsibility with no event attached, so it competes with everything that has a date and loses. What works instead is tying staleness to something already on a schedule you don’t control: your releases.
Which is a useful correction to how most teams picture this work. Documentation work doesn’t start when a release ships. It shouldn’t start at all, because it shouldn’t stop — releases are one input into it, alongside the questions, the search logs and everything else in this lesson.
The rule is one line, and it belongs wherever your team tracks work: when a release changes a screen, a flow, or an API response, the topics describing it get a task in the same batch. Not a review of the whole portal. Just the pages tied to what changed.
If your team tags releases by area, this is nearly free. If it doesn’t, the ten-minute version is a question in your release checklist: which existing pages describe what we just changed?
Nobody notices documentation going stale, because nothing happens when it does. Staleness needs a trigger, not an owner.
The trigger handles anything a release touches. Everything else — old topics that no feature has come near for two years — gets cleaned up in the quiet window after a major release, and in our interviews that window was the only time it ever happened. Plan for it rather than pretending old content is handled continuously. And let the signals pick which old area you spend the window on, instead of starting at the top of the list.
A queue by itself won’t get you time from your team. A documentation lead at an engineering software vendor (1000+ employees, Eastern Europe) put it flatly: “A new feature always wins.” That’s arithmetic, not dysfunction — feature work arrives with a date, a customer expectation and a name attached, and documentation work has none of those unless you give it some.
You give it some by connecting a documentation change to a behavior you can observe, and that behavior to something the business already tracks.
| Documentation change | Behavior it should shift | What the business already tracks |
| A job that had no entry point gets one | More trials complete that setup step | Activation |
| Troubleshooting for a known failure gets accurate | Fewer repeat contacts on the same issue | Support load per account |
| An advanced capability becomes explainable | More accounts use more of the product | Expansion, retention |
| Security and compliance answers are self-serve | Presales stops writing custom answers | Sales cycle length |
Nobody expects you to prove causality here, and you shouldn’t try. What you can do is much more modest and much harder to argue with:
That’s one row of evidence rather than a measurement program, and one row is the difference between “we should invest in docs” and “when we fixed the setup guide, twice as many trials finished setup.”
A documentation number that doesn’t connect to a behavior is a chore report. Pick the behavior first, then pick the number.
Two parts. The first maps where questions come from and where they end up.
| Where the question shows up | Where it lands | Who sorts it | Result |
| Search queries, especially no-result ones | Weekly list, with volume | Area owner | Doc fix or product item |
| Assistant conversations, especially the follow-ups | Same list | Area owner | Mostly product items |
| Support ticket | Doc issue, linked to the ticket | Area owner | Doc fix or product item |
| Onboarding, CS and presales questions | Same list | Area owner | Doc fix or product item |
| Release changes an area | Auto-created task on related topics | Whoever ships the release | Update or confirm still accurate |
The second is a shortlist. Five candidates, and you want three of them:
Everything in that list is countable without a new tool. Two of them are countable by hand in fifteen minutes a week.
Reading query logs properly and turning ticket data into a repeatable audit is real technique, and it belongs to whoever writes and maintains your documentation day to day. Our other course, 5 Steps to Smart Documentation, covers that.
What stays with you is the sorting. Nobody else in the company can look at a recurring question and decide whether it’s a page to write or a thing to fix in the product.
Do this for a month and you’ll have two things you didn’t have before: a documentation backlog with evidence attached, and a small pile of product findings nobody else was going to notice.
Then comes the part that catches people out. You can have accurate documentation, sorted signals, and a healthy backlog — and still find that your customers are getting answers about your product from somewhere else entirely, in a form you never wrote. That’s next.
The conversation happens; the trail doesn’t. Without a link back to the original ticket, every discussion restarts from opinion, and you can’t tell a one-off complaint from the fourth instance of the same problem.
Whoever is accountable for that part of the product — the same name from the ownership grid. It needs product judgment, not writing skill, and it takes minutes rather than hours.
Then the documentation has to carry it, and you should know that consciously rather than by default. A page written to compensate for a confusing flow is a legitimate decision. Writing it without noticing is not.
Cap it. Three metrics, one sorting pass a week, and no dashboard until someone asks for one twice.
Get monthly digest on technical writing, UX and web design, overviews of useful free resources and much more.
"*" indicates required fields
 How to Manage Multiple Product Manuals Without Duplicating Content
 Structuring documentation for multiple products: what to separate and what to share
 Release Notes & Changelog Automation: How to Stop Writing Manually
 Snippet Management in Technical Documentation: Stop Copy-Pasting, Start Reusing

