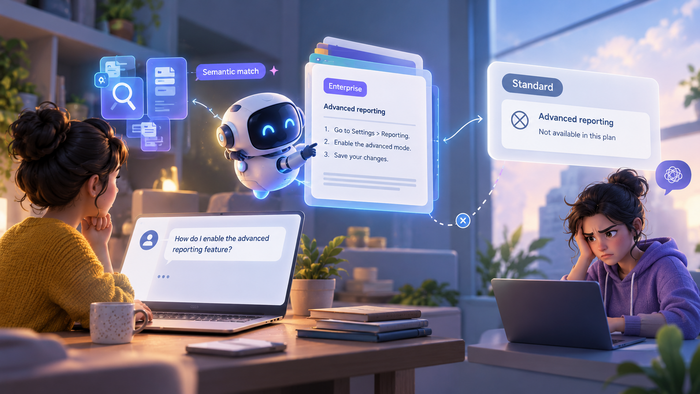
Here’s a scenario that plays out in support queues every day: a Standard-plan customer asks an AI assistant how to configure a feature. The AI pulls a textually relevant snippet from the Enterprise documentation. It explains the steps. The customer tries to follow them — and the feature doesn’t exist on the Standard plan. The customer is frustrated and loses trust in the product.
The AI answered correctly from a formal standpoint, but not appropriately. This is the blind spot of modern retrieval systems: semantic similarity is not the same as contextual applicability. The fix isn’t a smarter model — it’s metadata for retrieval.
Why a Correct Answer Isn’t Always the Right Answer
Ask a documentation team about a RAG failure and they’ll usually blame the LLM — a misunderstanding, a weak prompt. More often, the failure happens earlier, at the retrieval stage itself.
Here’s the mechanics: a vector embedding model converts text into a mathematical representation of meaning. “How to configure SSO” in the Standard docs and “How to configure SSO” in the Enterprise docs look almost identical in vector space. The model sees textual similarity and retrieves both: similarity alone doesn’t tell it that one fragment applies to this user’s permissions and the other doesn’t. Even an explicit line like “Enterprise only” at the top of the article helps only if it ends up in the same chunk and if something downstream actually checks it against the user’s plan — and neither is guaranteed.
That’s because applicability isn’t something the text carries on its own. A fragment can be a perfect semantic match for the question and still be wrong for this particular reader — because it’s the wrong version, written for the wrong audience, or describes a feature this user doesn’t have access to. Embeddings capture what the words mean; they don’t capture who the answer is for. That’s a separate signal, and it has to be supplied explicitly, as metadata, applied as a filter before the system starts comparing texts — not left for the model to guess at from a sentence buried in the middle of an article. Some pipelines also prepend key metadata to each chunk’s text so it shapes the embedding and stays visible to the LLM. That’s a useful complement, but it doesn’t replace filtering.
The Core Metadata Categories Documentation Needs
Metadata categories are structured attributes that describe a piece of content beyond its raw text. They don’t change the document’s body — they classify when, for whom, and in what situation that document is valid. Each field is a precision filter that narrows retrieval from “all documents” to “documents that actually apply to this specific user and their current goal.”
Five categories matter most:
- Product. Which product line, edition (such as Standard or Enterprise), subsystem, or architectural generation the content belongs to. This seems obvious until you work at a company with multiple product lines or legacy vs. modern architectures — a single “user management” guide might apply to three different products with subtly different UI paths. Without a product field, the retrieval system is guaranteed to make mistakes eventually.
- Version. The release number and its lifecycle status (current, deprecated, legacy). When v12 and v11 of the same feature are textually nearly identical, retrieval picks whichever fragment is closest to the query — which might be the one for the wrong release. A structured version field lets the system match content to the version the user actually runs, and prefer the current release only when the user’s version is unknown.
- Audience. The user role or skill level the content is written for. The same API endpoint might be documented for end users (business logic), administrators (permissions context), and developers (raw parameters) — three different documents that share a lot of vocabulary. Serve the developer-focused fragment to a non-technical user, and you get confusion, not help.
- Task / Intent. The user’s core purpose — setup, troubleshooting, reference, conceptual. “How do I set up SSO?” and “Why isn’t SSO working?” share the same vocabulary but need entirely different documents: a step-by-step guide versus a troubleshooting checklist. A task_type field lets the system retrieve by intent, not just keyword overlap. Unlike product or version, though, intent isn’t stored in a user profile — it has to be inferred from the query, and that inference can be wrong. That’s why task_type works better as a ranking signal than as a hard filter.
- Context / Environment. Situational variables that change applicability: deployment platform (cloud vs. on-premise), geographic region (GDPR vs. non-GDPR), integration status — anything that changes whether an instruction actually applies.
Together, these fields turn retrieval from “find text that looks like the question” into “find text that applies to this user’s situation.”
What Happens Without This Metadata
“The AI makes mistakes” is too abstract to act on. Without these fields, the failures are specific and predictable:
- The Standard-Enterprise trap. Enterprise-only information gets served to a Standard-plan user. They try to follow it, fail, blame themselves, and escalate to support — a product field would have stopped the wrong retrieval before it reached them.
- The novice-expert mismatch. A beginner’s basic setup question surfaces an API reference document, because it shares the same terms. They get buried in parameter descriptions and error codes meant for developers, and conclude the assistant is useless.
- The version trap. v11 and v12 guides for the same feature are nearly identical in text, even though the UI paths or config file locations have changed. Without a version field, which one gets served is a matter of luck.
- The internal-information leak. A support knowledge base that mixes internal troubleshooting notes with customer-facing content will surface both as equally relevant — and internal notes start showing up in customer replies. An audience: internal field reduces this risk, but a metadata filter is a weak security boundary: one mislabeled topic or one buggy query is enough for a leak. Internal content belongs in a separate index or behind access control at the storage level, with metadata as an extra layer on top.
None of these are hypothetical edge cases. They’re daily occurrences wherever documentation is treated as flat text instead of structured knowledge.
Where Metadata Actually Lives: Frontmatter, Tags, and Structured Fields
The most effective approach is frontmatter or custom fields at the topic level: dedicated fields for product, version, audience, task_type, and anything else relevant, defined in a modern help authoring tool. This is fundamentally different from mentioning the same thing in the text — a sentence like “This feature is available in Enterprise only” might influence the embedding, but it’s not a reliable filter. Textual mentions get chunked, sometimes separated from the rest of the content, and can be missed entirely by the retrieval system.
Taxonomy tags serve a related but distinct purpose. Tags like #database-configuration or #security are useful for categorizing content, but they’re applied inconsistently and lack the specificity of a field. A version field with a controlled vocabulary (current, deprecated) is a far more reliable signal than a tag like #v12.
Why does this need to be a structured field rather than something the system infers from text? Because retrieval systems work best when they can filter before semantic search, not after. If the system knows a user is on the Standard plan, it can filter to fragments with product: Standard before it even starts comparing embeddings — which reduces noise and ensures that whatever gets ranked is already applicable. Filtering after retrieval is also common, but it has a weakness: if most of the top results get filtered out, the system may be left with too few relevant fragments to answer well.
There’s a prerequisite here that’s easy to miss: filtering by metadata only works if the system knows the user’s context at query time. To filter by plan or version, the assistant needs that information — from authentication, a user profile, or the product session the question comes from. Without it, the safer move is to ask a clarifying question or fall back to unfiltered search with metadata used for ranking, rather than apply a hard filter that may return nothing at all. The same goes for topics where a field was never filled in: a strict filter silently excludes them.
Metadata and Chunking: Why It Has to Travel with Every Fragment
There’s a point most teams discover the hard way: metadata applied only at the document level doesn’t survive chunking.
When you index a long article, your pipeline splits it into smaller chunks (typically 500–1,000 tokens), so that each fragment covers one focused idea and can be matched precisely. If metadata is stored only at the document level and never explicitly propagated, individual chunks can lose that context entirely. A chunk from the middle of an Enterprise-only feature’s documentation might not contain the words “Enterprise only” anywhere in its own text. Retrieved on its own, that chunk gives the system no way to know who it applies to.
The fix requires implementation discipline, not a clever workaround: metadata has to be attached to every chunk, not just the parent document. Your indexing pipeline needs to explicitly copy the relevant fields — product, version, audience — from the topic level down to each chunk. If you chunk headers separately from body content, both need the parent topic’s metadata attached. Every chunk is a standalone unit once it’s in the retrieval index, and it needs its own context to be evaluated correctly.
A Practical Starter Checklist
| Field | Purpose | Example Values |
| product | Disambiguate content across product lines or editions | “Standard”, “Enterprise”, “OEM” |
| version | Distinguish current, deprecated, and legacy content | “12.4 (current)”, “11.3 (deprecated)” |
| audience | Match content to user role and expertise level | “end_user”, “administrator”, “developer”, “internal” |
| task_type | Distinguish intent: setup, troubleshooting, reference, conceptual | “setup”, “troubleshooting”, “reference” |
| environment | Capture deployment, region, and other conditions that change applicability | “cloud”, “on-premise”, “eu_gdpr” |
| last_reviewed | Signal freshness and recency | “2026-08-27” or a numeric freshness score |
This isn’t an exhaustive list — treat it as a starting point to adapt to your product’s actual structure, not a template to copy one-to-one. last_reviewed is worth calling out specifically: it isn’t about textual content at all, it’s about trust. A retrieval system can use it to favor recently reviewed content over an older fragment with stronger semantic similarity — particularly valuable for documentation where processes change regularly.
Common Mistakes
- Metadata exists only in the author’s head. Authors know which product a topic applies to but never record it anywhere structured. “We just know” doesn’t scale, and it doesn’t work for machine retrieval at all — the text is content, the metadata is context, and without context retrieval is just a word-matching exercise.
- Inconsistent controlled vocabularies. One topic uses Enterprise, another enterprise plan, a third ENT. Obviously the same thing to a person; completely different values to a filter. If you’re using a field, enforce a controlled vocabulary.
- Metadata that’s never updated. A topic accurate for v11 becomes misleading for v12, but its version field still says current. Metadata needs its own review cycle, on the same cadence as the content itself.
- Metadata at the document level but not the chunk level. This one is subtle — the system looks like it’s working until chunks from the middle of a topic start losing their context, and nobody notices until a customer gets the wrong answer.
The common thread across all four is treating metadata as an afterthought rather than as structured documentation metadata with the same review discipline as the content it describes.
Where This Fits in Your Documentation Workflow
Metadata belongs in the authoring workflow from the start, not bolted on afterward:
- Assignment during creation. When an author starts a new topic, they select product, version, audience, and task_type from a controlled vocabulary — part of authoring, not a separate admin step.
- Review during revision. When a topic changes, its metadata gets reviewed too: does it still apply to the same audience, is it still current, has the product category shifted?
- Ownership. Someone owns the metadata schema — defines the controlled vocabularies, checks consistency, and makes sure fields are actually being filled in correctly.
If you’re using a help authoring tool, you should be able to define custom properties for your topics — fields like product, version, and audience that travel with the content and are exposed through your API. A platform like ClickHelp helps here: structured fields at the topic level, managed centrally, instead of relying on manual text updates scattered across every article. Define the field once, authors fill it in, and the retrieval system consumes it consistently — which is really the whole point of documentation for AI agents in the first place.
Conclusion
The most common failure in AI-powered documentation isn’t the model, and it isn’t the retrieval algorithm. It’s the assumption that the text itself contains enough context for the system to know when it applies. It doesn’t. The text is content. The metadata is context. Without context, retrieval is just a word-matching exercise that happens to use vectors instead of keywords. With context, retrieval becomes a decision-making process that can distinguish between similar fragments and select the one that actually helps the user.
Good luck with your technical writing!
Author, host and deliver documentation across platforms and devices
FAQ
What’s the difference between tags and AI-ready metadata?
Tags are typically flat labels, inconsistently applied, and used for general organization. Even with a curated tag list, a tag only says that a topic relates to something; it doesn’t say which dimension that something belongs to. AI-ready metadata is structured as key–value pairs, uses controlled vocabularies, and is specifically designed to be consumed as filters in a retrieval pipeline. Tags say “this is about SSO.” Structured fields say “this applies to product X, version Y, and audience Z” — machine-parseable in a way tags aren’t.
Do I need metadata if I’m not using RAG yet?
Yes. Metadata improves search, content organization, and maintenance even without AI in the loop. More importantly, adding it retroactively is significantly harder than building it in from the start — if a retrieval-augmented generation context is even a possibility down the line, skipping metadata now is technical debt you’re choosing to take on.
How much metadata is too much?
More than 8–10 fields is usually overdoing it. The goal is covering the dimensions that actually differentiate applicability for your users — in most cases, product, version, audience, and task_type cover the vast majority of it. Add fields because you’ve observed a real failure pattern, not because a schema feels incomplete.
Can existing documentation be retrofitted with this metadata, or does it need to be planned from the start?
Both. Plan for it in new content, but don’t write off what already exists. A pragmatic approach is to start with your highest-traffic, highest-value content — the topics users ask about most — and expand coverage from there. It’s work, but retrieval improves incrementally as coverage grows, not only once everything is tagged.